A data platform team connects an analytics agent to the warehouse and gives it read access to every curated table. The first real test comes from the chief revenue officer: which enterprise customers churned last quarter? The agent returns one list on Monday, a slightly different list on Tuesday, and finance disagrees with both.
The post-mortem finds three separate problems. “Enterprise” exists in three places: a CRM segment field, a contract value threshold, and a plan tier, and the agent picked a different one each run. “Churned” meant the agent canceled a subscription and Finance revenue fell to zero. Several of the churned “customers” were regional subsidiaries of one parent company that renewed globally, so nothing was lost.
The first two problems are about how we calculate a number. The third is about what a customer is and how customers relate to each other. A semantic layer solves the first kind. The third needs an ontology. This blog explains the difference and when you need taxonomies, knowledge graphs, and a clean data model.
What Is the Difference Between an Ontology and a Semantic Layer?
An ontology defines business entities and their relationships, such as a customer, a parent company, and a contract, along with the rules that connect them. A semantic layer defines how business metrics are calculated from data, such as churn, revenue, or active users, so every tool and agent gets the same number.
Put more simply: the ontology answers “what is it?” and the semantic layer answers “how much of it?”
What is an ontology?
An ontology is a formal, machine-readable model of a domain. It names the classes of things that exist (Customer, Account, Contract, Product), the properties each one has, the relationships between them (an Account belongs to a Customer; a Customer may have a Parent Company), and the rules those relationships must follow (every Contract has exactly one billing Account). Because the model is formal, software can reason over it: if a subsidiary renews under its parent’s global contract, the ontology lets a system infer that the subsidiary’s relationship continues.
Ontologies are usually written in open standards from the World Wide Web Consortium, chiefly RDF for describing facts and OWL for describing classes and rules, though many enterprise teams now maintain lighter ontologies in their data catalog or graph platform.
What is a semantic layer?
A semantic layer is a governed set of metric and dimension definitions that sits between the data platform and everything that queries it: dashboards, spreadsheets, applications, and AI agents. It records what churned revenue means (recurring revenue from contracts not renewed within 30 days of expiry), which tables and joins produce it, which filters apply, and who can see it. Every consumer asks the semantic layer for “churned revenue by segment” instead of writing its own SQL, so the answer stays consistent.
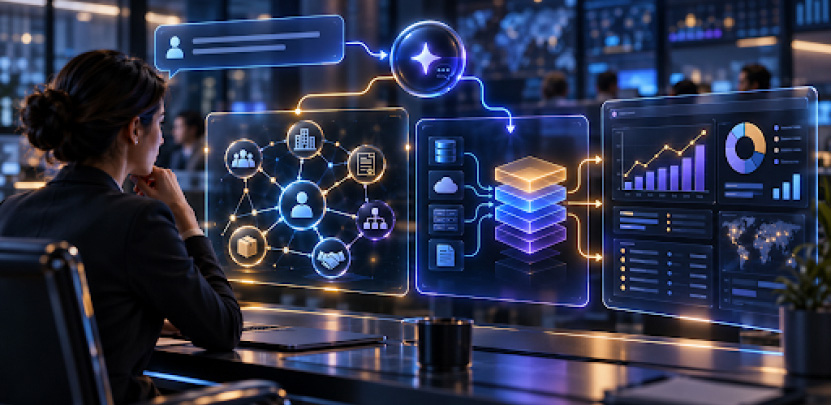
One Question, Five Layers: How Each Answers “Which Enterprise Customers Churned?”
Definitions blur together until you watch each layer handle the same request. Here is the chief revenue officer’s question, passed through the five structures an enterprise semantic architecture can include, from the bottom up.
1. The data model: where the facts are stored
The physical data model holds tables for accounts, subscriptions, invoices, and CRM opportunities, with keys that join them. It can tell the agent that a subscription row has an end date and a status column. It cannot tell the agent which status values count as churn, which of three “segment” columns is authoritative, or that two account rows belong to the same company. Without a clean data model, nothing above it works; with only a data model, every consumer interprets the columns its own way.
2. The semantic layer: how the number is calculated
The semantic layer defines the governed metric: churned customers are accounts whose recurring revenue drops to zero within the quarter and isn’t replaced by a renewal within 30 days. It also fixes the dimension: “enterprise” means the CRM segment field, not contract value or plan tier. Now Monday’s and Tuesday’s answers match, and they match finance. This resolves the first two problems from the opening.
3. The taxonomy: how things are classified
A taxonomy arranges the segments in a hierarchy: Enterprise splits into Strategic and Major, and Mid-Market splits into Upper and Core. It lets the chief revenue officer drill from Enterprise into Strategic accounts and lets the agent recognize that “strategic accounts” is a subset of the question. A taxonomy only knows parent-and-child relationships, though. It has no way to say that one account is a subsidiary of another.
4. The ontology: what a customer is and how customers relate
The ontology defines Customer as a legal entity that may have a Parent Company, says a Contract can cover the parent and all its subsidiaries, and states that a subsidiary covered by an active parent contract is not churned. With this, the agent sees that several “churned” accounts are subsidiaries consolidated under a global renewal and removes them from the answer. This resolves the third problem, and no metric definition could have done it.
5. The knowledge graph: the actual connected facts
The knowledge graph holds the instances the ontology describes: this specific subsidiary, its parent, the global contract signed in August, the account team, the open support escalations. Where the ontology supplies the rule, the graph supplies the facts the rule runs on. It also lets the agent go beyond the question asked: for customers who genuinely churned, it can show which shared a product line, an implementation partner, or an unresolved escalation.
The final answer combines all five: facts from the data model, the governed churn calculation from the semantic layer, the segment hierarchy from the taxonomy, the parent-subsidiary rule from the ontology, and the specific relationships from the knowledge graph.
Ontology vs Semantic Layer Comparison
| Ontology | Semantic layer | |
| Question it answers | What is this thing, and how does it relate to others? | How is this number calculated, and from which data? |
| Unit of definition | Classes, properties, relationships, and rules | Metrics, dimensions, joins, and filters |
| What it produces | Shared meaning and inferred facts | Consistent query results |
| Typical standards | RDF, OWL, SKOS, SHACL | Metric definitions in YAML or SQL, BI modeling languages |
| Who usually owns it | Data architects and domain experts, with knowledge engineers for formal models | Analytics engineers and BI teams, with finance and operations as metric owners |
| How often it changes | Slowly, when the business adds products, entities, or regulations | Often, as metrics, filters, and source tables change |
| How it fails | Models a business that no longer exists when not connected to live data | Calculates the right formula on the wrong or stale inputs |
| First value appears | After a domain is modeled and linked to data | As soon as the first metrics are governed and in use |
Two rows deserve attention. Change frequency explains why different teams usually own the two: metric definitions move with quarterly business reviews, while the meaning of “customer” or “contract” shifts with mergers, new product lines, and regulation. Failure mode explains why neither works alone for long. Each depends on the other staying accurate, and both depend on the underlying data model.
How Do the Related Terms Compare?
The ontology vs. semantic layer question usually comes up tangled with three others. Each has a short answer.
Ontology vs knowledge graph
An ontology is the schema; a knowledge graph is the data it shapes. The ontology says a Customer can have a Parent Company and that a Contract covers Accounts. The knowledge graph holds the actual customers, parents, contracts, and accounts as connected nodes. A knowledge graph can exist without a formal ontology, but it tends to drift: the same relationship gets recorded three ways, and cross-team queries stop returning complete results. The ontology keeps the graph consistent enough to trust.
Semantic layer vs data model
A data model describes how data is stored: tables, columns, data types, and keys. A semantic layer describes what the stored data means to the business and how to compute with it: metrics, dimensions, and the joins between them. The data model optimizes for storage and integrity; the semantic layer optimizes for consistent answers. A well-designed data model simplifies the semantic layer, and a semantic layer cannot fix a data model whose keys don’t join cleanly. Getting the model right starts with data engineering services that build pipelines with clear ownership and tested joins.
Taxonomy vs ontology vs semantic layer
A taxonomy classifies things into a hierarchy, such as product categories or customer segments. An ontology adds all other kinds of relationships and the rules governing them, so it can express that a product is sold under a contract to a customer in a regulated market. A semantic layer uses both as inputs: taxonomy levels become dimensions to slice metrics by, and ontology concepts become the entities metrics are calculated for. Most organizations already have taxonomies; they are the cheapest place to start formalizing meaning.
When Should You Use an Ontology, a Semantic Layer, or Both?
Use a semantic layer when the problem is inconsistent numbers, an ontology when the problem is inconsistent meaning or relationships across systems, and both when AI agents need to answer open-ended business questions. The fastest way to decide is to sort the questions your users and agents actually ask by their first words.
“How much,” “how many,” “what is the trend” → semantic layer. Revenue by region, churn by cohort, conversion by channel. These are calculations over governed definitions. If two dashboards disagree on any of them, the semantic layer fixes it.
“What is,” “which kind of,” “does this count as” → ontology. Is a reseller a customer? Does a pilot contract count as a sale? Is this subsidiary covered by the parent’s agreement? These depend on definitions and rules that cross systems, and they come up most in mergers, regulated industries, and anywhere the CRM, ERP, and billing system disagree about who the customer is. In healthcare, where a patient, a plan member, and a guarantor can be the same person recorded three ways, AI in healthcare projects often need an ontology first.
“What is connected to,” “who else,” “what would be affected” → knowledge graph governed by an ontology. Which suppliers feed the parts in this recalled product? Which customers share this implementation partner? These traverse relationships several steps deep, which tables and metric definitions handle poorly.
“Show me everything in” → taxonomy. Browsing product categories, filtering assets by data domain, or grouping customers by segment needs a hierarchy and little else.
Open-ended questions from AI agents → both. “Why did enterprise churn rise last quarter?” needs the governed churn metric, the meaning of enterprise and customer, and the relationships that might explain the change. This is where single-layer approaches run out.
If most of your current questions fall into the first group, start with the semantic layer. If your biggest arguments are about definitions rather than numbers, start with the ontology, even a lightweight one.
What Does an Enterprise Semantic Architecture Look Like?
An enterprise semantic architecture is a set of layers that turn stored data into shared, machine-usable meaning: a data model at the base; a semantic layer and an ontology side by side above it; a knowledge graph holding connected instances; and governance running through all of them. Analysts, applications, and AI agents query the top; the layers below keep their answers consistent.
A single universal semantic layer for the whole enterprise has proven hard to achieve. In February 2026 trend research, Gartner described data and analytics leaders pivoting toward a composite semantic layer: several semantic artifacts, owned by different teams and tools, coordinated to behave as one. Its 2026 data and analytics predictions go further, expecting universal semantic layers to be treated as critical infrastructure by 2030, alongside data platforms and cybersecurity.
In practice, four connections make a composite architecture behave as one system:
- Shared identifiers. Every ontology concept that a metric is calculated for, such as Customer or Contract, maps to a stable business key in the data model. When the semantic layer counts customers and the ontology reasons about customers, both point to the same entity. Without this, the two layers describe different things with the same word. Stable keys are hardest to establish in decades-old core systems, which is why semantic work often runs alongside legacy modernization.
- Explicit mappings. Each semantic layer entity and dimension declares which ontology class it implements, and each ontology class records which tables hold its instances. These mappings are where most integration work happens, and they should be reviewed like code.
- Linked change control. When finance redefines churn, the change request shows which ontology rules and downstream agents depend on it. When the ontology adds a new entity, such as a reseller, the semantic layer owners see which metrics need a new dimension. They review changes together instead of discovering them later. Versioning definitions and gating their changes the way code is gated follows the same logic that AI across the software development lifecycle applies to every artifact agents depend on.
- One access policy. Decide once who may see a customer’s contract value, and enforce it at every layer. If the semantic layer masks a field that the knowledge graph exposes, an agent will find the gap.
The platform underneath matters too. Teams that run analytics and AI on one governed copy of the data, often through data lakehouse architecture, have fewer places where definitions can silently diverge. A platform move is also the cheapest moment to consolidate definitions, so semantic cleanup belongs in any plan built around cloud migration. Systems designed with AI-native architecture go a step further and treat the ontology and semantic layer as design inputs from the first service.
Why Do AI Agents Need Both an Ontology and a Semantic Layer?
AI agents need a semantic layer to calculate numbers the business agrees with, and an ontology to understand what the words in a question refer to. When someone asks an analyst a vague question, they get a clarifying question back. An agent tends to pick an interpretation and answer confidently, which is how the opening scenario produced two different lists in two days. That holds whether the agent is built in-house or bought as AI as a service: the company remains responsible for the definitions it relies on.
The gap between AI ambition and data readiness is already visible. In the AI-ready data analysis, Gartner predicts that through 2026, organizations will abandon 60% of AI projects that lack AI-ready data. Shared meaning is a large part of what makes data AI-ready.
A well-grounded agent works through four steps for every business question:
- Resolve the terms. It uses the ontology to map “enterprise customers” to a defined class and segment, then applies rules, such as how subsidiaries roll up.
- Compute through governed definitions. It requests the churn metric from the semantic layer instead of writing its own SQL, so the number matches finance.
- Check access. It applies the same permission policy the semantic layer and graph enforce, scoped to the person asking. Giving the agent its own credentials and narrow rights is part of identity and access management for AI agents, and it matters more as agents start acting on answers instead of just reporting them.
- Show its work. It cites which metric definition and which ontology rules it used, so a reviewer can verify the answer in minutes. Logging those citations on every run is part of the AgentOps discipline of running agents in production.
Test this behavior before trusting it, the same way MLOps practices test a model against a fixed baseline before every release. A fixed set of business questions with known correct answers, rerun after every change to the ontology, semantic layer, or agent, is the most direct way to catch drift, and the same AI agent evaluation methods used for any production agent apply here.
How Should You Build It, and What Goes Wrong?
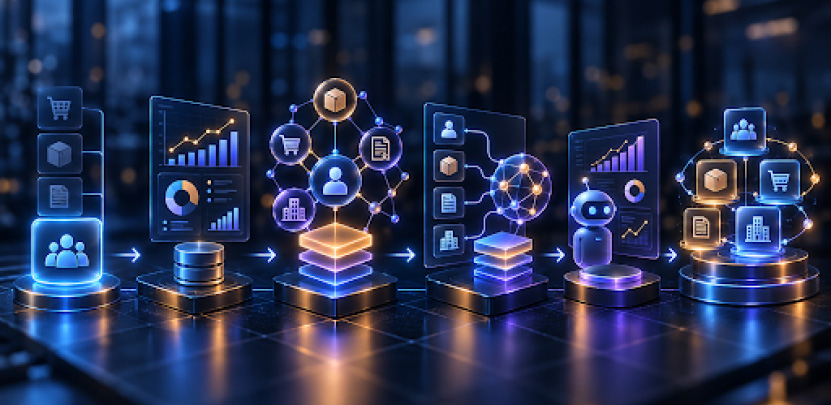
Build the semantic layer and a lightweight ontology for one business domain first, connect them through shared identifiers, and expand domain by domain. A company-wide model built before anyone uses it rarely survives contact with real questions.
A sequence that works for most enterprises:
- Pick one domain with a visible argument. Customer and revenue is the usual choice, because churn, bookings, and “who is the customer” disputes reach executives quickly.
- Govern the ten metrics that cause the most disagreement. Put them in the semantic layer, assign a named business owner to each, and retire conflicting dashboard versions.
- Write down the entities and rules behind those metrics. Start in plain language in the data catalog or glossary: what a customer is, how parents and subsidiaries relate, what counts as a contract. Formalize into an ontology standard once the definitions stop changing every week.
- Link them. Map each metric’s entities to ontology classes and both to stable business keys, and set up a shared review process for changes.
- Point one agent at the result and measure it. Run a fixed set of real questions, compare answers with what finance and operations accept, and fix the layer responsible for each miss. Teams practicing AI-native engineering keep these question sets beside their specs and rerun them on every change.
- Add the next domain. Product, supply chain, or people, depending on where the next agent or analytics use case is headed.
The mistakes that stall this work are consistent across industries:
- Modeling the whole enterprise up front. A complete ontology for every domain takes long enough that the business changes before it is finished. Model only what current questions need.
- Treating the semantic layer as a BI project. If only dashboards read from it, applications and agents will keep writing their own SQL. Expose it through APIs from day one.
- Leaving definitions without owners. A metric or ontology rule with no accountable business owner drifts the first time two teams disagree.
- Building in isolation. A semantic layer team and an ontology team that never share identifiers produce two vocabularies for the same business, which is the problem both were meant to solve.
Where this fits in a broader AI program depends on how mature the rest of the organization is. Scoring data, governance, and delivery capabilities against an AI maturity model shows whether semantic work is the constraint or whether something more basic, such as data access, needs to come first.
FAQs
Is a semantic layer an ontology?
No. A semantic layer defines how metrics are calculated from data. An ontology defines what business concepts mean and how they relate. Some semantic layers include light entity definitions, but they do not model relationships and rules in a way software can reason over.
Can a semantic layer replace an ontology for AI agents?
For simple questions about governed metrics, a semantic layer is often enough. For questions that depend on what a term means, how entities relate across systems, or rules such as how subsidiaries roll up to parents, an agent also needs an ontology.
What is the difference between an ontology and a knowledge graph?
An ontology is the schema that defines classes, relationships, and rules. A knowledge graph stores the actual entities and connections that follow that schema. The ontology describes what a customer can be; the knowledge graph holds every real customer and its relationships.
Where does a taxonomy fit compared to an ontology and a semantic layer?
A taxonomy is a hierarchy of categories, such as product lines or customer segments. An ontology extends it with other relationships and rules. A semantic layer uses taxonomy levels to slice metrics.
Which should we build first, an ontology or a semantic layer?
Start with the semantic layer if your main problem is conflicting numbers, and with a lightweight ontology if it is conflicting definitions of customers, products, or contracts. In either case, link the two through shared business identifiers early so they describe the same entities.
Why Choose [x]cube LABS?
[x]cube LABS works with enterprise teams to design and deploy AI agents across complex, regulated environments.
We help enterprises become AI-native, not by adding AI on top of existing systems, but by rebuilding the intelligence layer from the ground up. With 950+ products shipped and $5B+ in value created for clients across 15+ industries, here is what we bring to the table:
1. Autonomous AI Agents
We design and deploy agentic AI systems that sense, decide, and act without human bottlenecks, handling complex, multi-step workflows end-to-end with measurable resolution rates and no manual intervention.
2. Enterprise Voice AI
Our voice AI platform, Ello, puts production-ready voice agents in front of your customers in minutes. Zero-latency conversations across 30+ languages, with no call centers and no wait times.
3. AI-Powered Process Automation
We replace manual, error-prone workflows with intelligent automation across invoicing, compliance, customer service, and operations, freeing your teams to focus on work that requires human judgment.
4. Predictive Intelligence and Decision Support
Using machine learning and real-time data pipelines, we build systems that forecast demand, flag risk, optimize inventory, and surface strategic insights before your teams need to ask for them.
5. Connected Products and IoT
We design and build IoT platforms that turn physical devices into intelligent, connected systems with built-in real-time monitoring, remote management, and condition-based automation.
6. Data Engineering and AI Infrastructure
From data lakes and ETL pipelines to AI-ready cloud architecture, we build the foundation that makes everything else possible, scalable, reliable, and designed to grow with your business.
If you are looking to move from AI experimentation to AI-native operations, let’s talk.