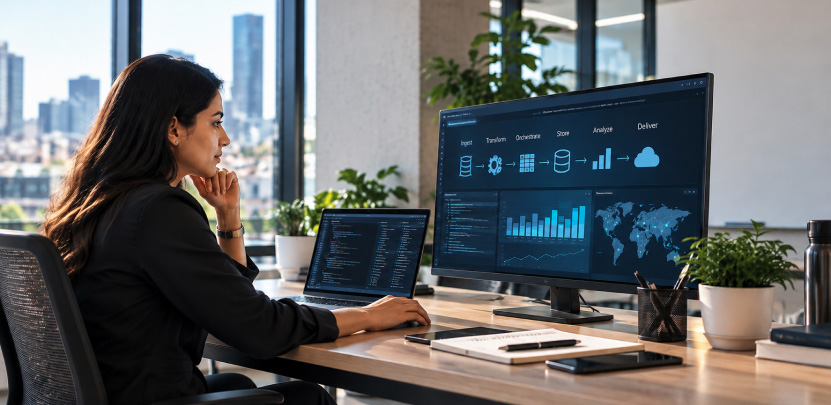
A retailer’s marketing team pulls a customer count from the CRM. Finance pulls a different customer count from the data warehouse for the same week. Both numbers are technically correct and describe different definitions of “customer.” Multiply that mismatch across a few hundred reports and a handful of AI pilots, and the cost stops being an argument about definitions and starts being real money: Gartner puts the average cost of poor data quality at $12.9 million a year per organization.
What Data Engineering Services Actually Cover
Data engineering services build and run the systems that move data from where it is generated to where it needs to be used: ingestion pipelines that pull data out of applications and devices, transformation logic that cleans and reshapes it, storage systems (warehouses, lakes, lakehouses) that hold it, and the governance layer that controls who can see and use what. The output is not a report. It is a dependable supply of data that analytics, dashboards, and AI systems can draw on without someone manually reconciling spreadsheets first.
Four capabilities show up in almost every engagement regardless of the provider: pipeline development for both batch and real-time data, storage and architecture design, data quality and governance, and integration with the analytics or AI systems the data ultimately feeds. A provider that only does one of these, pipelines without governance, or storage without pipelines, tends to hand a client a system that works until it does not.
Why “Every Enterprise” Is Not an Exaggeration
Every enterprise generates more data sources than it did five years ago: more SaaS applications, more IoT devices, more customer touchpoints, each with its own format and update cadence. Left uncoordinated, this produces exactly the kind of mismatch described above, and it is expensive. Gartner’s $12.9 million figure spans rework, missed opportunities, and decisions made on numbers that later turn out to be wrong.
The cost has gotten sharper in the AI era. Gartner predicts organizations will abandon 60% of AI projects that are not backed by AI-ready data, which means the data engineering work is not a supporting function for an AI initiative; it is the load-bearing wall. A model trained or run against inconsistent, disconnected, or stale data will not produce the outcomes a pilot demo promised, no matter how capable the model itself is.
Data Engineering vs. Data Science vs. Data Analytics
These three terms get used almost interchangeably in job postings and vendor pitches, and the distinction matters when scoping a project.
Data engineering builds and maintains the infrastructure and pipelines that make data usable: the plumbing. Data analytics interprets that data to answer specific business questions, typically through dashboards and reports. Data science builds predictive and machine learning models on top of it. Each depends on the one before it: a data scientist cannot build a reliable model on data a pipeline never cleaned, and an analyst cannot trust a dashboard built on ungoverned data. Most projects that stall midway stall because this order got reversed: a model or dashboard got built before the underlying data engineering work was done.
What Good Data Engineering Looks Like in the AI Era
The bar has moved since data engineering meant nightly batch jobs feeding a dashboard that refreshed once a day. Three shifts matter most for enterprises evaluating a provider today.
Real-time over batch.
Change data capture and streaming pipelines now do a meaningful share of the work older nightly ETL jobs used to. A fraud check or an inventory alert running on yesterday’s data is not useful today.
Data built for AI consumption, not just dashboards.
AI systems query data differently than a person building a report does. Vector and hybrid search, a semantic layer that gives every metric one consistent definition, and retrieval architecture an AI agent can reason over are now part of a modern data engineering scope, not an add-on.
Convergence instead of duplication.
Running separate systems for transactional and analytical workloads, then copying and syncing between them, is exactly the kind of sprawl that produces the mismatched-numbers problem. Modern architecture increasingly converges the two rather than maintaining parallel copies that drift apart.
Build In-House vs. Bring In a Data Engineering Services Partner
An in-house team offers institutional knowledge of the business’s specific systems and full control over roadmap and priorities. It also means hiring and retaining a skill set- pipeline engineering, data architecture, governance- that is expensive and in short supply, and building it from scratch typically takes longer than most AI or analytics initiatives can wait.
A services partner brings a team and a set of patterns already tested elsewhere, which shortens the path to a working data foundation. The tradeoff is the same one true of any outsourced capability: institutional knowledge of a business’s specific quirks takes time to build regardless of who does the work. The engagements that work best treat the partner as building the foundation and transferring capability to an internal team, not as a permanent external dependency.
Who Owns Data Engineering Inside the Enterprise
Even a fully outsourced build needs internal owners, or the work has no one to hand off to once the contract ends. Four roles show up in engagements that hold up over time: a data architect who owns the target design and makes the build-versus-buy calls on individual components, a governance or data steward who owns access policy and quality standards, a platform engineer who keeps pipelines running day to day, and a business sponsor who can prioritize which data sources or use cases matter most when the roadmap has to narrow. None of these need to be new hires; they are frequently existing staff with the role made explicit rather than assumed.
What to Look for in a Data Engineering Services Provider
A few questions separate a provider that delivers a working data foundation from one that delivers a project that needs rebuilding in two years.
Do they design for the AI and analytics use cases you actually have, not a generic reference architecture?
A semantic layer or vector search capability that was never scoped is a gap that shows up later, expensively.
Do they build governance in from the start?
Access control, data lineage, and quality monitoring retrofitted after a breach or a bad report cost more than the same work done during the build.
Can they show a system running in production, not just a proof of concept?
Pipelines are easy to demo and hard to keep reliable at production volume over years. Ask what broke and how it was caught.
Do they transfer capability, or create dependency?
A provider whose contract ends with your team unable to operate what they built has not finished the engagement.
Common Data Engineering Mistakes
Building pipelines before defining the questions they need to answer.
Data engineering scoped without a specific analytics or AI use case in mind tends to produce infrastructure nobody uses.
Treating governance as a compliance checkbox.
Access control and data lineage exist to make data trustworthy enough to act on, not just to pass an audit.
Migrating everything at once.
A big-bang migration of every data source into a new platform multiplies the risk of every individual migration. Sequencing by business value, highest-impact source first, contains the damage when something breaks.
Skipping the semantic layer.
Without one consistent definition of a core metric, every new dashboard or AI system risks recreating the mismatched-numbers problem this article opened with.
FAQ
What is the difference between data engineering and data engineering services?
Data engineering is the discipline. Data engineering services describe hiring an outside team, a consultancy, managed provider, or specialized platform, to design, build, or operate that infrastructure rather than building the capability entirely in-house.
Do small and mid-size enterprises need data engineering services, or only large enterprises?
Data volume and source count matter more than company size. A mid-size company running a dozen SaaS tools and an AI pilot has the same mismatched-data problem as a much larger one; it just shows up on a smaller budget.
How long does a data engineering services engagement typically take?
A scoped initial build, a pipeline and storage foundation for one or two priority use cases, typically runs a few months. Ongoing operation and expansion to new data sources is ordinarily a standing engagement rather than a fixed end date.
Does data engineering matter if we are not building AI systems yet?
Yes. Clean, governed, well-structured data improves reporting and decision-making on its own. It also means the AI initiative that eventually gets proposed will not need to start from zero on the data side.
What is a semantic layer, and why does it matter?
A semantic layer is a single, governed definition of each business metric- revenue, active customer, churn- that every dashboard, report, and AI system draws from. Without one, different teams calculate the same metric differently and get different numbers from the same underlying data.
How [x]cube LABS Can Help
Data is the second of the nine capabilities [x]cube LABS builds AI programs around, and for good reason: stalled AI initiatives almost always trace back to data that was not current, connected, or queryable in the ways AI requires. The practice covers AI-ready data foundations and lakehouse builds, real-time change data capture, convergence of transactional and analytical workloads onto one architecture, and the semantic layer and vector search work that let both dashboards and AI agents draw from one governed source of truth.
That foundation is what made a supply chain authentication platform work for a global agricultural company operating in 100+ countries, catching counterfeits in the field rather than in an audit, and what let a national diagnostics network scale its order-processing pipeline roughly 100-fold, from about 2,000 to more than 30,000 daily orders, without the platform buckling under the new volume. Both engagements started with the same premise: the data foundation gets built first, and the analytics and AI use cases layer on top of it, not the other way around.
Talk to someone who has actually built this.