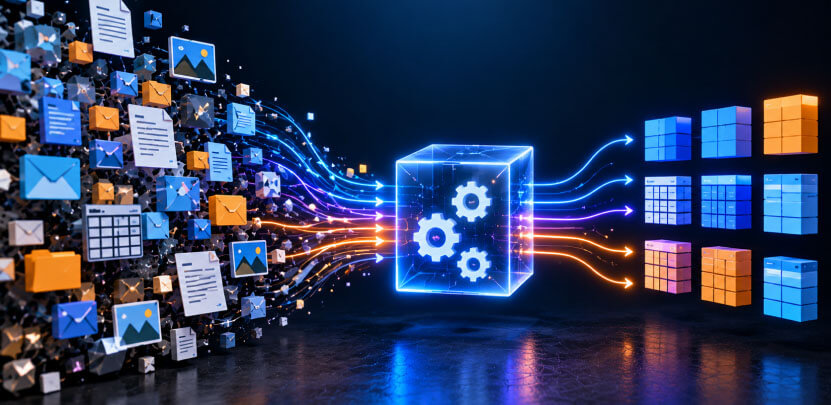
Data rarely shows up in the shape a business needs. Sales records come from one system, product events from another, and customer details from a spreadsheet someone built years ago. Each source has its own formats, naming habits, and gaps. Before any of it can power a report, a dashboard, or a model, someone has to reshape it into something consistent and trustworthy.
That reshaping work is data transformation, and it quietly sits underneath almost every analytics and AI initiative. This blog explains what it is, how the data transformation process works, the main types and techniques, and where it shows up in real projects, with examples you can adapt to your own stack.
What Is Data Transformation?
Data transformation is the process of changing data’s format, structure, values, or granularity so it fits the system and the purpose that will use it. Cleaning a messy field is a transformation. So is joining two tables, converting currencies, summing daily sales, masking an email address, or turning a PDF invoice into rows.
The definition hides an important point: data has no single correct shape. The finance team needs one row per order in a reporting currency. The forecasting model needs daily totals per product. The support agent needs the latest order per customer with personal data masked. One source feeds many transformed outputs, and each output is defined by who consumes it.
Transformation runs in three places in a modern data stack:
- Before loading (ETL): Data is extracted, transformed on a separate processing layer, then loaded into the target. Common when sensitive fields must never land in the warehouse unmasked.
- After loading (ELT): Raw data lands in a cloud warehouse or lakehouse first and is transformed there with SQL. This is now the analytics default because the raw data stays available for reprocessing.
- In motion (streaming): Transform each event as it arrives for use cases such as fraud checks or live inventory, where minutes of delay matter.
Most organizations use all three, and the platform underneath shapes the choice. Teams that run analytics and machine learning on one copy of the data tend to choose data lakehouse architecture, where raw, cleaned, and business-ready layers sit side by side, and every transformation between them is traceable.
Why Data Transformation Matters
Untransformed data causes problems quietly. Reports disagree, joins fail because keys don’t match, and models learn from noise. The cost is real: Gartner research puts the average annual cost of poor data quality at $12.9 million per organization, a figure drawn from its 2020 research that remains widely cited.
The stakes are rising with AI. In a 2025 release, Gartner predicted that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data. The same release cited a survey of 1,203 data management leaders in which 63% said they either lack, or are unsure they have, the right data management practices for AI.
In practical terms, well-run data transformation gives you:
- Consistency: The same customer, product, or metric means the same thing everywhere.
- Compatibility: Data fits the schema of the warehouse, lakehouse, or application receiving it.
- Trust: Validated, documented data that analysts and models can rely on.
- Speed: Less time spent fixing data by hand before every analysis.
The Data Transformation Process: 6 Steps
The exact workflow varies by team and tooling, but most data transformation projects follow the same arc.
1. Discover and profile the source data
Start by finding out what you actually have. Catalog the sources (databases, APIs, files, event streams), then profile them: data types, value ranges, null rates, duplicate rates, and how keys relate across systems. Do not trust file extensions or column names alone. Look at the values.
2. Define the target and map the fields
Decide what the output should look like, including schema, grain (one row per order? per customer per day?), naming conventions, and data types. Then build the data mapping that connects each source field to its target field and records the rule applied. A mapping document is also your first piece of documentation.
3. Clean and validate
Fix what is broken before reshaping it: remove duplicates, handle missing values, correct obvious errors, and standardize formats. Add validation rules here, such as allowed value lists, range checks, and uniqueness checks on keys.
4. Transform
Apply the actual logic: type conversions, joins, aggregations, derivations, encoding, normalization, and enrichment. This logic lives in SQL, Python, Spark, or a visual tool, ideally in version-controlled code rather than ad hoc scripts.
5. Load and verify
Write the results to the target system and confirm they are correct. Compare row counts, check totals against the source, and spot-check records. Reconciliation catches silent errors that logic-only tests can miss.
6. Monitor and document
Transformations break when upstream data changes. Add freshness, volume, and schema-change alerts, record lineage (where each field came from), and keep the mapping and business rules current. Not every dataset needs every step. Occasionally, a clean source can be used as is, but you should reach that conclusion through profiling, not assumption.
Types of Data Transformation
Data transformation falls into four families: cleaning, structuring, combining, and deriving or protecting.
| Cleaning | Data cleansing | Fixes or removes inaccurate, incomplete, or outdated records | Correcting New ork to New York |
| Cleaning | Deduplication | Removes repeated records | Keeping one row per order_id |
| Cleaning | Imputation | Fills missing values with plausible ones | Replacing missing ages with the median |
| Cleaning | Validation | Checks data against rules | Rejecting negative quantities |
| Structural | Format conversion | Changes data types, encodings, or file formats | CSV to Parquet; string to timestamp |
| Structural | Splitting and parsing | Breaks one field into several | Address into street, city, postal code |
| Structural | Flattening | Turns nested data into tabular form | JSON event payload into columns |
| Structural | Pivoting and unpivoting | Rotates rows and columns | Monthly columns into a month field |
| Value-level | Normalization | Rescales values to a common range | Scaling prices to 0–1 |
| Value-level | Standardization | Rescales to zero mean and unit variance | Z-scores for model inputs |
| Value-level | Log and power transforms | Reduce skew in distributions | Log of income values |
| Value-level | Binning (discretization) | Groups continuous values into buckets | Age into age bands |
| Integration | Joining and merging | Combines tables on shared keys | Orders joined to customers |
| Integration | Enrichment | Adds context from other sources | Appending firmographic data to leads |
| Integration | Key restructuring | Replaces meaningful keys with surrogate keys | Generating a customer ID |
| Reduction | Aggregation | Summarizes detail into totals or averages | Daily sales into monthly revenue |
| Reduction | Filtering | Keeps only relevant records | Dropping test accounts |
| Feature-level | Encoding categoricals | Converts categories to numbers | One-hot encoding of plan type |
| Feature-level | Feature construction | Derives new variables | Days since last purchase |
A few of these are worth understanding in depth
Normalization vs. standardization: People use these words interchangeably, but they differ. Normalization squeezes values into a fixed range, usually 0 to 1. Standardization centers values around zero with a standard deviation of one. Distance-based models such as k-nearest neighbors and clustering tend to be sensitive to scale, so you usually need one of the two. Tree-based models generally are not.
Data aggregation: Aggregation reduces detail to answer a question at the right level: transactions to daily revenue, sessions to weekly active users. The key decision is the grain, and aggregating too early destroys detail you may want later. Many teams keep raw, lightly cleaned data and aggregate it in a separate layer.
Data enrichment: Enrichment adds information you did not collect yourself, such as geographic data, industry classifications, or currency rates. It improves analysis, but every enrichment source adds a dependency and a quality risk, so track where it came from.
Encoding: Models need numbers. One-hot encoding creates a column per category and works well for low-cardinality fields. For high-cardinality fields such as product IDs, teams often use target encoding or learned embeddings instead.
Data Transformation Techniques: ETL, ELT, and Beyond
The best way to understand the main data transformation techniques is by where and when the transformation happens.
ETL vs. ELT
| Order | Extract, transform in a staging area, then load | Extract, load raw data, then transform inside the target |
| Where compute runs | Separate transformation server or tool | The warehouse or lakehouse itself |
| Best for | Strict compliance needs, sensitive data masked before loading, smaller structured datasets | Large or varied data, cloud platforms, fast iteration |
| Raw data kept? | Often not | Yes, which lets you re-transform later |
| Typical tools | Informatica, Talend, SSIS | dbt, Spark SQL, warehouse-native SQL |
ETL is still the right call when you must mask or remove sensitive fields before data lands in the target. ELT has become the default for cloud analytics because modern warehouses and lakehouses have the compute to transform data where it already sits, and keeping raw data means you can fix a logic mistake without re-extracting anything. If you are moving to the cloud, our guide to cloud migration strategies covers how that shift fits into the wider plan.
Batch vs. streaming
Batch transformation processes data in scheduled chunks, such as hourly or nightly. It is simpler and cheaper, and it suits reporting. Streaming transformation processes events as they arrive, which suits fraud detection, live dashboards, and operational alerts. Many teams run both. A useful rule: do not pay for streaming unless a decision genuinely needs to be made within seconds or minutes.
Layered (medallion) architecture
A common way to organize transformation is in layers. Raw data lands in a bronze layer, gets cleaned and conformed in silver, and is shaped into business-ready tables in gold. Each layer has one job, which makes problems easier to isolate. This pattern is central to the data lakehouse approach, which combines a data lake’s flexibility with a warehouse’s structure.
Incremental transformation
Reprocessing everything on every run gets slow and expensive as data grows. Incremental transformation processes only new or changed records, using a timestamp, change data capture, or a high-water mark. It requires careful handling of late-arriving data and updates, but it is usually essential at scale.
Data Transformation Examples
Theory only goes so far. These data transformation examples show what the work looks like in practice.
Example 1: Cleaning and standardizing order data (SQL)
A retailer receives orders from a point-of-sale system and an e-commerce platform. Emails have inconsistent casing, a retry bug duplicates some orders, and dates arrive as text. A transformation into a clean silver table might look like this (the QUALIFY clause is supported in Snowflake, BigQuery, and Databricks):
SELECT
CAST(order_id AS BIGINT) AS order_id,
LOWER(TRIM(customer_email)) AS customer_email,
CAST(order_ts AS TIMESTAMP) AS ordered_at,
COALESCE(country_code, ‘UNKNOWN’) AS country_code,
amount
FROM bronze.orders_raw
WHERE order_id IS NOT NULL
QUALIFY ROW_NUMBER() OVER (
PARTITION BY order_id ORDER BY updated_at DESC
) = 1;
Before and after:
| 1042 | Asha.R@Mail.com | 03/11/2026 | asha.r@mail.com | 2026-11-03 |
| 1042 | asha.r@mail.com | 03/11/2026 | removed as a duplicate |
Note that a date like 03/11/2026 is ambiguous (March 11 or 3 November). Resolving that ambiguity from the source system’s documented format, not a guess, is exactly the kind of decision transformation work involves.
Example 2: Cleaning, aggregating, and imputing in Python
An analyst needs monthly revenue from a messy export:
import pandas as pd
df = pd.read_csv(‘orders_raw.csv’)
df[‘order_date’] = pd.to_datetime(df[‘order_date’], format=’%d/%m/%Y’, errors=’coerce’)
df[’email’] = df[’email’].str.strip().str.lower()
df = df.drop_duplicates(subset=’order_id’)
df[‘amount’] = df[‘amount’].fillna(df[‘amount’].median())
monthly = (
df.dropna(subset=[‘order_date’])
.groupby(df[‘order_date’].dt.to_period(‘M’))[‘amount’]
.sum()
)
This single script uses format conversion, deduplication, imputation, filtering, and aggregation. Median imputation is a reasonable default, but it can distort results if many values are missing, so check how many rows it touches.
Example 3: Healthcare record standardization
A hospital network merges patient records from several facilities. Each uses different codes for the same diagnosis and procedure, and names appear in different formats. Transformation maps local codes to a shared standard, normalizes identifiers, and links duplicate patient records. For analytics, teams pseudonymize or remove direct identifiers so they can study outcomes without exposing personal data. This is a case where transformation must happen before data reaches the broader analytics environment, favoring an ETL-style approach. See how this plays out across our healthcare work.
Example 4: Feature engineering for fraud detection
A payments team stores one row per transaction, but a fraud model needs behavioral signals. Transformation aggregates each customer’s history into features such as transaction count in the last hour, average amount over 30 days, number of distinct merchants this week, and the ratio of today’s spend to the 30-day average. These are rolling-window aggregations, then joined back to each transaction. Getting the time boundaries right matters: using future data in a feature (leakage) makes a model look brilliant in testing and fail in production.
Example 5: Flattening product event data
A SaaS product emits JSON events like {“user”:{“id”:7},”event”:”export”,”props”:{“format”:”csv”}}. Transformation flattens the nesting into columns (user_id, event_name, export_format), assigns session IDs by grouping events with gaps under 30 minutes, and aggregates into daily usage tables for product analytics.
Example 6: Preparing documents for an AI assistant
Transformation is not only for tables. To build a retrieval-augmented generation (RAG) assistant, teams extract text from PDFs and wikis, clean boilerplate, split content into chunks, attach metadata such as source and access permissions, and convert chunks into vector embeddings. The same principles apply: clean inputs, consistent structure, and tracked lineage. For a broader view of how this fits into enterprise AI, see our guide to what enterprise AI is.
Data Transformation for AI and Machine Learning
AI raises the bar. A dashboard can tolerate an occasional odd row, but a model trained on skewed or leaky data will repeat the flaw at scale. ML pipelines add their own transformation needs: train/validation/test splits, consistent feature calculation between training and serving, handling of class imbalance, and tracking of dataset versions.
That last point is where data work meets operations. If features are computed differently in training and production, accuracy degrades without any obvious error. A solid MLOps practice addresses this with shared feature definitions, versioned datasets, and drift monitoring. If you are unsure how ready your data foundations are for AI, an AI maturity model can help you assess where to invest first.
Data transformation also underpins larger modernization efforts. When you move off aging platforms, the hardest part is often not the application but the data: untangling years of inconsistent formats, undocumented fields, and hidden dependencies. Our guide to legacy modernization covers how to sequence that work without disrupting operations.
How to Get Started
If you are building or improving your transformation layer, a sensible path looks like this:
- Pick one high-value use case, such as a revenue dashboard or a churn model, rather than trying to fix everything at once.
- Profile the required sources and document the target schema and business definitions.
- Build the pipeline with tests and a clear raw-to-clean-to-business layering.
- Add monitoring and lineage from day one, not after the first incident.
- Review cost and performance, then repeat for the next use case.
Our Data and ML engineering services team supports this kind of work, from designing pipelines and lakehouse architecture to getting data ready for production AI.
Frequently Asked Questions
1) What is data transformation in simple terms?
It is the process of converting raw data into a clean, consistent, usable format so you can analyze it, store it, or feed it into applications and models.
2) What are the main steps in the data transformation process?
Discover and profile the data, define the target and map fields, clean and validate, apply the transformations, load and verify the results, then monitor and document.
3) What is the difference between data cleansing and data transformation?
Cleansing fixes errors, such as duplicates, typos, and missing values. Transformation is a broader process that includes cleansing, plus restructuring, joining, aggregating, enriching, and encoding data.
4) What is the difference between ETL and ELT?
In ETL, data is transformed before loading into the target system. In ELT, you load raw data first and transform it in the target, usually a cloud warehouse or lakehouse.
5) What are examples of data transformation?
Converting date formats, removing duplicate records, aggregating daily sales into monthly totals, joining orders to customers, one-hot encoding categories, and flattening JSON events into columns.
6) Which tools are used for data transformation?
Common choices include dbt and warehouse SQL, Apache Spark and Databricks, Python with pandas, ETL platforms such as Informatica, Talend, and Qlik, and orchestrators such as Airflow.
Conclusion
Data transformation is less glamorous than the dashboards and models it feeds, but it decides whether they can be trusted. Start with a clear target, profile your sources honestly, choose ETL or ELT based on your constraints, test every layer, and document what you build. Teams that treat transformation as a core engineering discipline, rather than a cleanup chore, spend less time arguing about numbers and more time acting on them.
Why Choose [x]cube LABS?
[x]cube LABS works with enterprise teams to design and deploy AI agents across complex, regulated environments.
We help enterprises become AI-native, not by adding AI on top of existing systems, but by rebuilding the intelligence layer from the ground up. With 950+ products shipped and $5B+ in value created for clients across 15+ industries, here is what we bring to the table:
1. Autonomous AI Agents
We design and deploy agentic AI systems that sense, decide, and act without human bottlenecks, handling complex, multi-step workflows end-to-end with measurable resolution rates and no manual intervention.
2. Enterprise Voice AI
Our voice AI platform, Ello, puts production-ready voice agents in front of your customers in minutes. Zero-latency conversations across 30+ languages, with no call centers and no wait times.
3. AI-Powered Process Automation
We replace manual, error-prone workflows with intelligent automation across invoicing, compliance, customer service, and operations, freeing your teams to focus on work that requires human judgment.
4. Predictive Intelligence and Decision Support
Using machine learning and real-time data pipelines, we build systems that forecast demand, flag risk, optimize inventory, and surface strategic insights before your teams need to ask for them.
5. Connected Products and IoT
We design and build IoT platforms that turn physical devices into intelligent, connected systems with built-in real-time monitoring, remote management, and condition-based automation.
6. Data Engineering and AI Infrastructure
From data lakes and ETL pipelines to AI-ready cloud architecture, we build the foundation that makes everything else possible, scalable, reliable, and designed to grow with your business.
If you are looking to move from AI experimentation to AI-native operations, let’s talk.